Blei, D. M., Ng, A. Y., & Jordan, M. I. (2003). Latent Dirichlet Allocation. Journal of Machine Learning Research, 3, 993–1022.
Brundage, M. P., Sexton, T., Hodkiewicz, M., Dima, A., & Lukens, S. (2021). Technical Language Processing: Unlocking Maintenance Knowledge.
Manufacturing Letters,
27, 42–46.
https://doi.org/10.1016/j.mfglet.2020.11.001
Cavnar, W. B., & Trenkle, J. M. (1994). N-Gram-Based Text Categorization. Proceedings of the Third Annual Symposium on Document Analysis and Information Retrieval (SDAIR-94), 161–175.
Deerwester, S., Dumais, S. T., Furnas, G. W., Landauer, T. K., & Harshman, R. (1990). Indexing by latent semantic analysis. Journal of the American Society for Information Science, 41(6), 391–407.
Harris, Z. S. (1954). Distributional Structure.
Word,
10(2–3), 146–162.
https://doi.org/10.1080/00437956.1954.11659520
Joachims, T. (1998). Text categorization with Support Vector Machines: Learning with many relevant features. Machine Learning: ECML-98, Lecture Notes in Computer Science, 1398, 137–142.
Lee, D. D., & Seung, H. S. (1999). Learning the parts of objects by non-negative matrix factorization. Nature, 401(6755), 788–791.
Levy, O., & Goldberg, Y. (2014). Neural Word Embedding as Implicit Matrix Factorization. Advances in Neural Information Processing Systems 27, 2177–2185.
Manning, C. D., Raghavan, P., & Schütze, H. (2008). Introduction to Information Retrieval. Cambridge University Press.
McCallum, A., & Nigam, K. (1998). A Comparison of Event Models for Naive Bayes Text Classification. AAAI-98 Workshop on Learning for Text Categorization, 41–48.
Mihalcea, R., & Tarau, P. (2004). TextRank: Bringing Order into Texts. Proceedings of the 2004 Conference on Empirical Methods in Natural Language Processing, 404–411.
Mikolov, T., Chen, K., Corrado, G., & Dean, J. (2013). Efficient Estimation of Word Representations in Vector Space. arXiv:1301.3781.
Orosz, G., Szabó, G., Berkecz, P., Szántó, Z., & Farkas, R. (2023). Advancing Hungarian Text Processing with HuSpaCy: Efficient and Accurate NLP Pipelines. arXiv:2308.12635.
Orosz, G., Szántó, Z., Berkecz, P., Szabó, G., & Farkas, R. (2022). HuSpaCy: an industrial-strength Hungarian natural language processing toolkit. arXiv:2201.01956.
Porter, M. F. (1980). An algorithm for suffix stripping. Program, 14(3), 130–137.
Salton, G., & Buckley, C. (1988). Term-weighting approaches in automatic text retrieval. Information Processing & Management, 24(5), 513–523.
Spärck Jones, K. (1972). A Statistical Interpretation of Term Specificity and Its Application in Retrieval.
Journal of Documentation,
28(1), 11–21.
https://doi.org/10.1108/eb026526
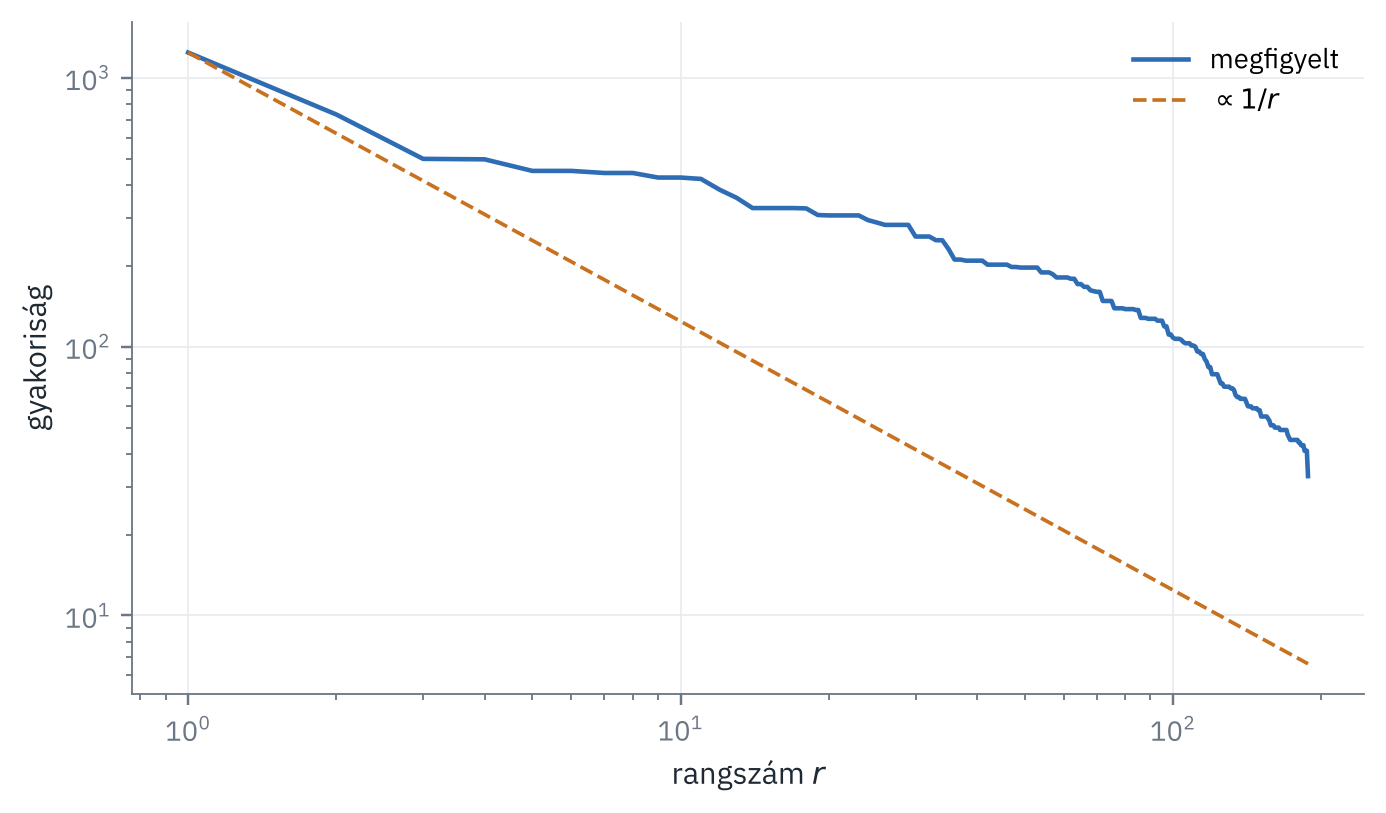
Zipf, G. K. (1949). Human Behavior and the Principle of Least Effort. Addison-Wesley.